Does the order of the passages change Jev's pick?
I reversed, shuffled and renamed the thirty passages, changed the answer labels, and checked what Jev's confidence says about which picks hold.
On this page
In plain words: reverse the order of the thirty passages, and Jev picks a different top passage on about one query in five to one in four. The exact share depends on how I asked it. When Jev rates its own confidence at 0.9 or above, its top pick changes on only 4.0% of those queries. But that score isn't the chance of being right. By the datasets' labels, answers scored 0.90 to 0.95 were right 85.5% of the time, and answers scored 0.99 and above, 98.4%.
In my reranking benchmark, I gave TypeSafe's Jev thirty search results per query and used its answers to put the useful ones first. On ranking quality it kept up with Cohere Rerank 4 Pro. That leaves a different question: show Jev the same passages in a different order, or under different names, and does it still pick the same one?
I reversed, shuffled and renamed the passages, repeated identical requests, and changed the labels on the answer options. Then I checked whether Jev's own confidence tells you which picks hold still. These results first appeared on September 17 as an update to the benchmark article; they have their own page since September 23.
#What I measured
Every test here reuses the 1,617 queries from the benchmark that have at least one passage labelled relevant among their thirty candidates. The candidates are the same, each cut to 2,000 characters. The original and reversed Choice responses are from September 16; the new repeats, shuffles, and label experiments are from September 17. The saved responses give the model version as jev-1.13.0.
Jev answered in the same four setups as in the benchmark:
| Setup | What I ask Jev |
|---|---|
| Yes/no, shared request (Noul) | Thirty relevance questions, with all thirty passages in the shared state. |
| Choice | One choice among thirty passages and “none,” plus a separate question about whether any passage answers the query. |
| Rubric, shared request (Score) | Thirty questions asking whether each passage is off-topic, related, partly useful, or fully useful. |
| Yes/no, isolated passage (Noul) | One passage and its relevance question per request; thirty requests per search query. |
Setup
Yes/no, shared request (Noul)
- What I ask Jev
- Thirty relevance questions, with all thirty passages in the shared state.
Choice
- What I ask Jev
- One choice among thirty passages and “none,” plus a separate question about whether any passage answers the query.
Rubric, shared request (Score)
- What I ask Jev
- Thirty questions asking whether each passage is off-topic, related, partly useful, or fully useful.
Yes/no, isolated passage (Noul)
- What I ask Jev
- One passage and its relevance question per request; thirty requests per search query.
One distinction runs through everything below: ranking a passage first and choosing an answer are different measurements. Jev Choice can answer “none” and still give every passage a probability.
| Original Choice run, all 1,617 scored queries | Label-supported outcomes |
|---|---|
| Highest-ranked passage, ignoring “none” | 1,229 / 1,617 — 76.0% |
| Actual returned answer, including “none” | 1,135 / 1,617 — 70.2% |
Original Choice run, all 1,617 scored queries
Highest-ranked passage, ignoring “none”
- Label-supported outcomes
- 1,229 / 1,617 — 76.0%
Actual returned answer, including “none”
- Label-supported outcomes
- 1,135 / 1,617 — 70.2%
The ranking tables in the benchmark use the first definition, and so do the ranking flips below. The answer-correctness tables below use the second. “Correct” throughout means supported by the dataset's labels; passages nobody labelled count as not relevant.
#Confidence identifies a more stable subset
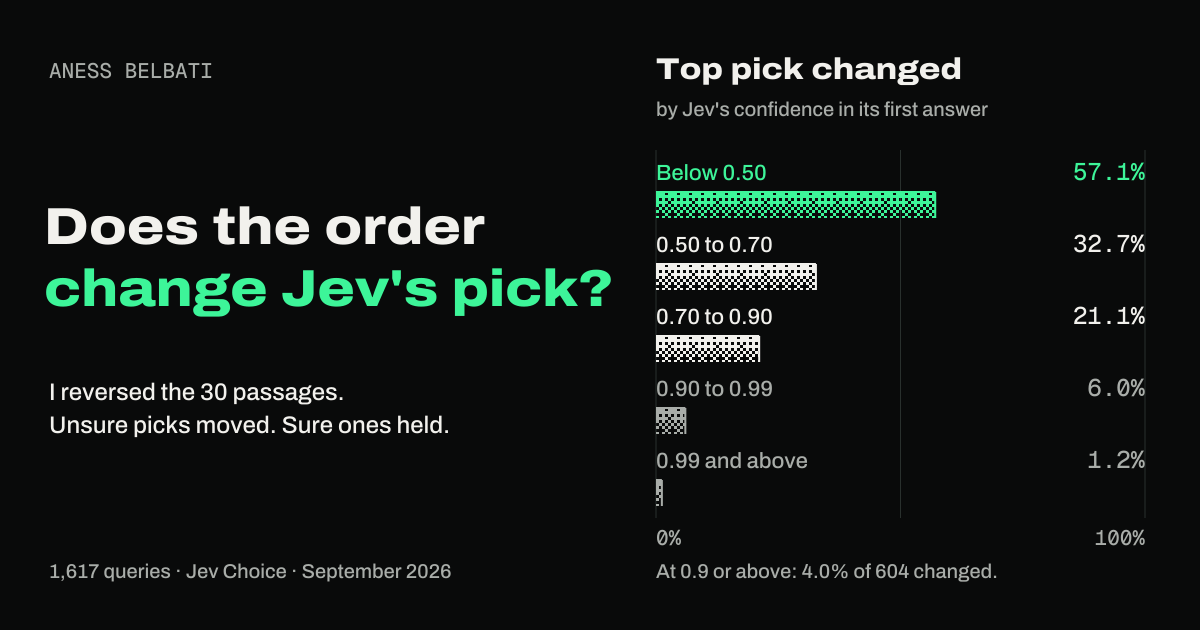
In short: the surer Jev is, the less reversing the passages moves its pick. Below 0.50 confidence, 57.1% of picks changed; at 0.99 and above, 1.2%.
Here I group queries by Jev's confidence in its first answer, then check whether reversing the passages changes the highest-ranked passage. That confidence is known before the second call, so the grouping doesn't peek at the result.
| Original Choice confidence | Queries | Highest-ranked passage changed |
|---|---|---|
| Below 0.50 | 345 | 197 / 345 — 57.1% |
| 0.50 to below 0.70 | 327 | 107 / 327 — 32.7% |
| 0.70 to below 0.90 | 341 | 72 / 341 — 21.1% |
| 0.90 to below 0.99 | 352 | 21 / 352 — 6.0% |
| 0.99 and above | 252 | 3 / 252 — 1.2% |
Original Choice confidence
Below 0.50
- Queries
- 345
- Highest-ranked passage changed
- 197 / 345 — 57.1%
0.50 to below 0.70
- Queries
- 327
- Highest-ranked passage changed
- 107 / 327 — 32.7%
0.70 to below 0.90
- Queries
- 341
- Highest-ranked passage changed
- 72 / 341 — 21.1%
0.90 to below 0.99
- Queries
- 352
- Highest-ranked passage changed
- 21 / 352 — 6.0%
0.99 and above
- Queries
- 252
- Highest-ranked passage changed
- 3 / 252 — 1.2%
At confidence 0.9 or above, the highest-ranked passage changes on 24 of 604 queries (4.0%), compared with 400 of 1,617 overall. That group covers 37.4% of this set. The other 62.6% still need a plan: another model, more evidence, a person checking, or no answer at all. Setting them aside doesn't fix their rankings.
The confidence belongs to Jev's actual answer, which can be “none.” Within the same 604-query group, the actual answer changes on 17 queries (2.8%). By the labels, that answer is right on 563/604 (93.2%) in the original order and 556/604 (92.1%) after reversal. Those numbers are about answers, not the ranking flips above.
September 17 follow-up
What survives a confidence filter?
Raise the minimum returned confidence, then inspect which questions remain and how often reversing the candidate order changes the top-ranked passage.
These 1,617 queries come from the eight English datasets. Each has at least one labelled-relevant passage among its original thirty candidates. Answer-removed lists are excluded.
Loading the recorded questions…
Of the 400 ranking flips, 101 swap one labelled-relevant passage for another, and 98 swap one passage without a relevant label for another. Another 111 turn a right top pick into a wrong one, while 90 do the reverse. So about half the flips change whether the top pick is right, and the gains and losses partly cancel: ranking accuracy moves from 76.0% to 74.7%.
The least confident group holds 197 of the 400 flips (49.3%). A near-tie between the top two passages is another warning sign: when their probabilities are less than 0.05 apart, 77 of 115 queries (67.0%) flip.
Reversing changed Jev's pick more often than any other order change I tried. Two random shuffles disagree on 302/1,617 queries (18.7%). Averaging two orders and comparing with the average of the other two gives flip rates of 13.7%, 16.1%, and 16.8% across the three possible pairings. Together they average 15.5%, but the three pairings reuse the same queries, so they aren't three independent measurements.
Ranking accuracy is 76.2%–76.5% with two orders averaged and 77.3% with four. Another option is to ask a second time, in another order, only when confidence is below 0.9. That needs a second call for 62.6% of queries. Run with other orders, the same rule still picks a different top passage on 14.0% of queries. Averaging and a confidence cut-off are trade-offs to measure, not fixes.
#The same order test across modes
In short: when Jev sees all thirty passages at once, reversing them changed its top pick on about a fifth to a quarter of queries, depending on the setup. The small Qwen model's top pick changed on 92.6%.
A ranking flip means a different passage gets the highest score; ties keep the original keyword-search (BM25) order. The score-gap column counts only the flips where either run scores its own top passage at least 0.10 more than the other run's top passage, so near-ties drop out. The order report calls these “real flips.” (Computer rounding can make a gap that should be exactly 0.10 come out a hair under it, so gaps within 1e-10 of 0.10 still count.) Read that column as a rough guide. Choice, Noul and rubric scores mean different things, so the same gap isn't the same size of mistake in each.
| Setup | Reversal: ranking flips | With score gap ≥0.10 | Labelled correctness changed | Same input asked again: ranking flips | Original top passage labelled relevant |
|---|---|---|---|---|---|
| Jev Choice | 24.7% | 22.9% | 12.4% | 2.9% | 76.0% |
| Jev, 30 yes/no questions in one request | 19.6% | 6.0% | 8.8% | 5.7% | 74.3% |
| Jev, 30 rubric questions in one request | 18.6% | 3.5% | 8.5% | 4.6% | 74.6% |
| Jev, one yes/no request per passage | Not applicable | Not applicable | Not applicable | 6.5% | 71.2% |
| Qwen recipe, 30 yes/no questions | 92.6% | 91.4% | 27.1% | Not measured | 13.6% |
Setup
Jev Choice
- Reversal: ranking flips
- 24.7%
- With score gap ≥0.10
- 22.9%
- Labelled correctness changed
- 12.4%
- Same input asked again: ranking flips
- 2.9%
- Original top passage labelled relevant
- 76.0%
Jev, 30 yes/no questions in one request
- Reversal: ranking flips
- 19.6%
- With score gap ≥0.10
- 6.0%
- Labelled correctness changed
- 8.8%
- Same input asked again: ranking flips
- 5.7%
- Original top passage labelled relevant
- 74.3%
Jev, 30 rubric questions in one request
- Reversal: ranking flips
- 18.6%
- With score gap ≥0.10
- 3.5%
- Labelled correctness changed
- 8.5%
- Same input asked again: ranking flips
- 4.6%
- Original top passage labelled relevant
- 74.6%
Jev, one yes/no request per passage
- Reversal: ranking flips
- Not applicable
- With score gap ≥0.10
- Not applicable
- Labelled correctness changed
- Not applicable
- Same input asked again: ranking flips
- 6.5%
- Original top passage labelled relevant
- 71.2%
Qwen recipe, 30 yes/no questions
- Reversal: ranking flips
- 92.6%
- With score gap ≥0.10
- 91.4%
- Labelled correctness changed
- 27.1%
- Same input asked again: ranking flips
- Not measured
- Original top passage labelled relevant
- 13.6%
All rows use the same 1,617 queries, with each query weighted equally. This differs from the benchmark's headline tables, which weight each dataset equally. The Qwen reversal results are the original saved control from the benchmark's Qwen test, not a newly repeated run.
Per 1,000 queries, the original calls cost an estimated $0.34 for Jev Choice, $0.43 for thirty yes/no questions in one request, $0.46 for thirty rubric questions in one request, and $0.80 for one yes/no request per passage. The estimates use the saved API usage and the prices I assumed. Qwen's $0.08 counts only the GPU time its runs used, not start-up or idle time, so it isn't what running Qwen for real would cost. I haven't checked any of these against an invoice.
Like for like, with thirty yes/no questions each, Jev's top pick changed on 19.6% of queries and Qwen's on 92.6%. Whether the top pick was right changed on 8.8% for Jev and 27.1% for Qwen. That's about this small Qwen model, recipe and prompt. It doesn't show that larger models, or other ways of forcing a model to answer only yes or no, would do as badly.
When all thirty passages share one request, the scores still depend on their order, in both the yes/no and the rubric setup, even though each passage gets its own question. Many of those changes are near-ties, but a near-tie can still put an unlabelled passage above a labelled answer.
When Jev sees one passage per request, there's no order to reverse, so that row has no reversal result: not applicable, not zero. Sending those requests again still changes the highest-ranked passage on 105/1,617 queries (6.5%), though none of those changes clears the 0.10 gap. Small score changes and the tie rule still matter.
The repeat comparisons span September 16 and 17, so they mix Jev's run-to-run variation with any change to the service between those days. The order report calls them the “noise floor.” Read them as a rough measure of how much Jev's answers vary when the input stays the same, not a clean baseline. Among the original 604 high-confidence Choice queries, the highest-ranked passage changed on one repeated request.
#Criterion labels and option order
In short: the words on the two answer options, and which comes first, can move Jev's scores. Swapping YES and NO moved 1.5% of passage scores by 0.10 or more; swapping X and Y moved 17.5%.
A report from a user on TypeSafe's Discord prompted this check. I have left them unnamed. The measurements here are from my own saved runs, not a rerun of their examples.
I kept the relevance instruction and the descriptions of the two answers fixed, and changed only the labels on the answers: YES/NO, A/B, X/Y and RELEVANT/IRRELEVANT, each in both orders. With Noul and exact duplicates of Noul and YES/NO, that makes 11 variants per passage. Each request, one per search query, held all thirty passages and 330 questions, which gives 48,510 passage scores per variant. This tests labels and their order, not other wordings of the instruction.
| Comparison | Mean absolute probability difference | Passage scores differing by ≥0.10 |
|---|---|---|
| YES/NO versus its exact duplicate | 0.005 | 0.1% |
| YES/NO options swapped | 0.009 | 1.5% |
| A/B options swapped | 0.012 | 2.5% |
| RELEVANT/IRRELEVANT options swapped | 0.013 | 3.2% |
| X/Y options swapped | 0.061 | 17.5% |
| A/B instead of YES/NO | 0.009 | 1.0% |
| X/Y instead of YES/NO | 0.027 | 7.0% |
| RELEVANT/IRRELEVANT instead of YES/NO | 0.029 | 11.3% |
| Choice YES/NO versus Noul | 0.055 | 14.8% |
Comparison
YES/NO versus its exact duplicate
- Mean absolute probability difference
- 0.005
- Passage scores differing by ≥0.10
- 0.1%
YES/NO options swapped
- Mean absolute probability difference
- 0.009
- Passage scores differing by ≥0.10
- 1.5%
A/B options swapped
- Mean absolute probability difference
- 0.012
- Passage scores differing by ≥0.10
- 2.5%
RELEVANT/IRRELEVANT options swapped
- Mean absolute probability difference
- 0.013
- Passage scores differing by ≥0.10
- 3.2%
X/Y options swapped
- Mean absolute probability difference
- 0.061
- Passage scores differing by ≥0.10
- 17.5%
A/B instead of YES/NO
- Mean absolute probability difference
- 0.009
- Passage scores differing by ≥0.10
- 1.0%
X/Y instead of YES/NO
- Mean absolute probability difference
- 0.027
- Passage scores differing by ≥0.10
- 7.0%
RELEVANT/IRRELEVANT instead of YES/NO
- Mean absolute probability difference
- 0.029
- Passage scores differing by ≥0.10
- 11.3%
Choice YES/NO versus Noul
- Mean absolute probability difference
- 0.055
- Passage scores differing by ≥0.10
- 14.8%
Of the pairs I tested, swapping the order mattered most for X/Y. Sending that same request again for 200 queries gave a similar shift, and the X/Y shifts for each passage matched closely across the two runs (correlation 0.87).
Inside that request, Noul's scores differed from the original Noul scores by 0.006 on average, the same, after rounding, as simply asking again. So I found no sign that putting all the variants in one request shifts scores on average. That doesn't rule out effects on individual passages, or a small consistent bias.
Grouped by each passage's original Noul score, from the separate first run, here is how far apart the four standard Choice label pairs scored it:
| Original Noul score | Passages | Mean label-pair spread | Spread ≥0.30 |
|---|---|---|---|
| Below 0.10 | 32,754 | 0.009 | 0.0% |
| 0.10 to below 0.30 | 7,748 | 0.074 | 0.5% |
| 0.30 to below 0.70 | 4,834 | 0.254 | 32.9% |
| 0.70 to below 0.90 | 1,850 | 0.160 | 6.0% |
| 0.90 and above | 1,324 | 0.032 | 0.0% |
Original Noul score
Below 0.10
- Passages
- 32,754
- Mean label-pair spread
- 0.009
- Spread ≥0.30
- 0.0%
0.10 to below 0.30
- Passages
- 7,748
- Mean label-pair spread
- 0.074
- Spread ≥0.30
- 0.5%
0.30 to below 0.70
- Passages
- 4,834
- Mean label-pair spread
- 0.254
- Spread ≥0.30
- 32.9%
0.70 to below 0.90
- Passages
- 1,850
- Mean label-pair spread
- 0.160
- Spread ≥0.30
- 6.0%
0.90 and above
- Passages
- 1,324
- Mean label-pair spread
- 0.032
- Spread ≥0.30
- 0.0%
The labels mattered most for passages in the middle of the score range, the ones Jev was unsure about. Clear yeses and clear noes barely moved in this test. These are per-passage probabilities, not the Choice answer-confidence groups above.
| Variant | Mean probability | AUROC | Query-weighted nDCG@10 | Scores ≥0.9 labelled relevant |
|---|---|---|---|---|
| Noul | 0.155 | 0.906 | 0.736 | 61.4% |
| RELEVANT/IRRELEVANT | 0.147 | 0.901 | 0.734 | 50.5% |
| YES/NO | 0.118 | 0.888 | 0.729 | 53.5% |
| A/B | 0.117 | 0.888 | 0.729 | 55.2% |
| X/Y | 0.116 | 0.880 | 0.733 | 59.6% |
| X/Y, options swapped | 0.176 | 0.864 | 0.713 | 56.8% |
| Average of the eight Choice variants | 0.135 | 0.888 | 0.725 | 55.2% |
Variant
Noul
- Mean probability
- 0.155
- AUROC
- 0.906
- Query-weighted nDCG@10
- 0.736
- Scores ≥0.9 labelled relevant
- 61.4%
RELEVANT/IRRELEVANT
- Mean probability
- 0.147
- AUROC
- 0.901
- Query-weighted nDCG@10
- 0.734
- Scores ≥0.9 labelled relevant
- 50.5%
YES/NO
- Mean probability
- 0.118
- AUROC
- 0.888
- Query-weighted nDCG@10
- 0.729
- Scores ≥0.9 labelled relevant
- 53.5%
A/B
- Mean probability
- 0.117
- AUROC
- 0.888
- Query-weighted nDCG@10
- 0.729
- Scores ≥0.9 labelled relevant
- 55.2%
X/Y
- Mean probability
- 0.116
- AUROC
- 0.880
- Query-weighted nDCG@10
- 0.733
- Scores ≥0.9 labelled relevant
- 59.6%
X/Y, options swapped
- Mean probability
- 0.176
- AUROC
- 0.864
- Query-weighted nDCG@10
- 0.713
- Scores ≥0.9 labelled relevant
- 56.8%
Average of the eight Choice variants
- Mean probability
- 0.135
- AUROC
- 0.888
- Query-weighted nDCG@10
- 0.725
- Scores ≥0.9 labelled relevant
- 55.2%
AUROC measures how often a passage labelled relevant scores higher than a passage without a relevant label, with ties counting half. On that scale, 0.5 is a coin flip and 1 is perfect. nDCG@10 scores how well the top ten are ordered. Noul had the highest AUROC and nDCG@10 of the standard variants here, though I haven't measured how much of these differences is noise. Averaging the eight Choice variants didn't beat Noul either.
Choice YES/NO scored about 0.038 lower than Noul on average, but individual passages differed by more, and other labels behaved differently. If you set a threshold, keep the question type, labels and order fixed: there's no fixed amount you can add to turn one kind of score into another.
#Renaming passages in Choice
In short: renaming the passages changed Jev's top pick on 4.3% to 5.5% of queries, against 2.9% for simply asking again. Shuffling the passages changed it far more often.
This is a separate experiment with the pick-one question and the same relevance instruction. The passages are normally named p01, p02 and so on; here I renamed them with numbers, letters or random four-character codes.
| Passage identifiers and run | Top passage labelled relevant | Actual answer correct at that run's confidence ≥0.9 | Ranking changed versus original |
|---|---|---|---|
| p01, original | 76.0% | 93.2% | Baseline |
| p01, repeated | 75.6% | 91.9% | 2.9% |
| Numbers, original order | 76.3% | 92.4% | 4.3% |
| Letters, original order | 76.2% | 93.0% | 4.7% |
| Random four-character codes, original order | 76.2% | 92.9% | 5.5% |
Passage identifiers and run
p01, original
- Top passage labelled relevant
- 76.0%
- Actual answer correct at that run's confidence ≥0.9
- 93.2%
- Ranking changed versus original
- Baseline
p01, repeated
- Top passage labelled relevant
- 75.6%
- Actual answer correct at that run's confidence ≥0.9
- 91.9%
- Ranking changed versus original
- 2.9%
Numbers, original order
- Top passage labelled relevant
- 76.3%
- Actual answer correct at that run's confidence ≥0.9
- 92.4%
- Ranking changed versus original
- 4.3%
Letters, original order
- Top passage labelled relevant
- 76.2%
- Actual answer correct at that run's confidence ≥0.9
- 93.0%
- Ranking changed versus original
- 4.7%
Random four-character codes, original order
- Top passage labelled relevant
- 76.2%
- Actual answer correct at that run's confidence ≥0.9
- 92.9%
- Ranking changed versus original
- 5.5%
Across the four naming runs with the passages shuffled, ranking accuracy ranged from 75.1% to 76.1%. Answers in each run's own high-confidence group were right 92.5% to 94.8% of the time. Those groups can hold different queries, so this doesn't mean every high-confidence query kept its answer under every naming.
For the 466 queries with original confidence of 0.95 or more, all four naming schemes, in the original passage order, gave the same highest-ranked passage. Below confidence 0.5, they agreed on 68.4%. Renaming mattered less than shuffling here, but it wasn't zero.
Checking the saved responses also turned up three near-ties where the answer Jev returned wasn't the passage it gave the highest probability. That's one more reason to keep the returned answer and the ranking apart.
#What confidence can tell me about correctness
In short: higher confidence usually means a right answer more often, from 40.9% below 0.50 to 98.4% at 0.99 and above. But the score isn't the chance of being right.
TypeSafe describes confidence as a number computed from how Jev's probability is spread across the possible answers. It is not defined as the chance that the answer is right. These groups show how confidence relates to correctness; they don't show that confidence 0.90 means 90% right.
The rates below score the answer Jev actually returned, including “none.” To see what Jev does when no labelled answer is in the list, I also made answer-removed lists. I took out every passage labelled relevant and refilled each list with the next keyword-search (BM25) results. Some of those may still be relevant, since the labels aren't complete. The last column, a 95% Wilson interval, shows how far each rate could plausibly move with a different sample of the same size.
| Condition, confidence ≥0.9 in that run | Label-supported answers | Observed rate | 95% Wilson interval |
|---|---|---|---|
| Original lists with a labelled answer | 563 / 604 | 93.2% | 90.9%–95.0% |
| All labelled-relevant passages removed | 204 / 359 | 56.8% | 51.7%–61.8% |
| Both constructed conditions pooled | 767 / 963 | 79.6% | 77.0%–82.1% |
| Reversed lists, selected by reversed-run confidence | 546 / 586 | 93.2% | 90.8%–94.9% |
Condition, confidence ≥0.9 in that run
Original lists with a labelled answer
- Label-supported answers
- 563 / 604
- Observed rate
- 93.2%
- 95% Wilson interval
- 90.9%–95.0%
All labelled-relevant passages removed
- Label-supported answers
- 204 / 359
- Observed rate
- 56.8%
- 95% Wilson interval
- 51.7%–61.8%
Both constructed conditions pooled
- Label-supported answers
- 767 / 963
- Observed rate
- 79.6%
- 95% Wilson interval
- 77.0%–82.1%
Reversed lists, selected by reversed-run confidence
- Label-supported answers
- 546 / 586
- Observed rate
- 93.2%
- 95% Wilson interval
- 90.8%–94.9%
The pooled row mixes the two kinds of list in this experiment's proportions, so it isn't an estimate for any real application. Of the 1,617 queries, 1,609 have an answer-removed version; one NFCorpus and seven TREC-COVID queries don't. The ranges only cover the luck of which queries were sampled; they don't cover missing labels, passages shared between queries, or the choice of datasets.
For the original lists containing a labelled answer:
| Reported confidence | Queries | Mean confidence | Actual answer labelled correct |
|---|---|---|---|
| Below 0.50 | 345 | 0.38 | 40.9% |
| 0.50 to below 0.60 | 171 | 0.54 | 53.2% |
| 0.60 to below 0.70 | 156 | 0.64 | 69.2% |
| 0.70 to below 0.80 | 152 | 0.75 | 65.1% |
| 0.80 to below 0.90 | 189 | 0.85 | 70.4% |
| 0.90 to below 0.95 | 138 | 0.92 | 85.5% |
| 0.95 to below 0.99 | 214 | 0.97 | 92.1% |
| 0.99 and above | 252 | 1.00 | 98.4% |
Reported confidence
Below 0.50
- Queries
- 345
- Mean confidence
- 0.38
- Actual answer labelled correct
- 40.9%
0.50 to below 0.60
- Queries
- 171
- Mean confidence
- 0.54
- Actual answer labelled correct
- 53.2%
0.60 to below 0.70
- Queries
- 156
- Mean confidence
- 0.64
- Actual answer labelled correct
- 69.2%
0.70 to below 0.80
- Queries
- 152
- Mean confidence
- 0.75
- Actual answer labelled correct
- 65.1%
0.80 to below 0.90
- Queries
- 189
- Mean confidence
- 0.85
- Actual answer labelled correct
- 70.4%
0.90 to below 0.95
- Queries
- 138
- Mean confidence
- 0.92
- Actual answer labelled correct
- 85.5%
0.95 to below 0.99
- Queries
- 214
- Mean confidence
- 0.97
- Actual answer labelled correct
- 92.1%
0.99 and above
- Queries
- 252
- Mean confidence
- 1.00
- Actual answer labelled correct
- 98.4%
The rise isn't smooth: answers at 0.70 to 0.80 were right less often (65.1%) than answers at 0.60 to 0.70 (69.2%). And the ≥0.9 group mixes 85.5% in the 0.90–0.95 slice with better results above it. Any cut-off picked from these tables still needs testing on new data and on the questions a real application gets.
A quick first check of fourteen answers from the answer-removed lists reported twelve relevant picks, one probably relevant and one unclear. Those fourteen weren't chosen or judged in a documented, independent way. So I don't use them to correct the 56.8% figure, or to estimate how many errors are really missing labels. How often Jev is truly right, not just right by the labels, is still unmeasured.
The datasets label very different numbers of passages. In this query set, Natural Questions has about 1.3 passages labelled relevant per query across its collection, versus about 493 in TREC-COVID. Even TREC-COVID's labels aren't a complete answer key. When Jev sees one passage per request (Noul), the share of scores of 0.9 or above that are labelled relevant is 34.5% on Natural Questions and 98.5% on TREC-COVID. The two datasets also differ in task and candidates, so this doesn't show that the labels alone cause the gap.
That makes calibration numbers slippery. A well-calibrated score of 0.9 would be labelled relevant about 90% of the time. Expected calibration error measures how far the scores miss that, against the labels available; lower is better. Across all the queries, X/Y's error is lower than Noul's (0.042 versus 0.075); on TREC-COVID alone it's higher (0.292 versus 0.247). So these numbers don't tell you which variant's scores best match true relevance on new data.
#Follow-up evidence and limits
The interactive rows contain both passage rankings and actual Choice answers, with input-file hashes. The order report, label report, and confidence report are saved analysis printouts, not raw model responses. Their shorthand such as “right,” “real flip,” or “noise floor” should be read with the definitions above.
The benchmark checkout contains the original cache/ responses, the follow-up order_runs/ and label_runs/ responses, the candidate labels, and the analysis scripts scripts/order_flips.py, scripts/label_eval.py, and scripts/calib_pooled.py. Those inputs, rather than this article's tables alone, are needed to reproduce the results.
These are early results for one model version, one relevance instruction and queries from selected public datasets. I don't know whether Jev saw these datasets in training. I looked at the thresholds on this same sample only; I haven't tested an automatic rule on real traffic it hasn't seen. The label tests don't cover other instruction wordings, prediction questions, other languages or future model versions. The idea from the benchmark post, scoring each passage on several questions at once (does it support the claim, does it contradict it), is still untested.
The ranking comparison itself, with Cohere Rerank 4 Pro, zerank-2, the costs and the negation test, is in I gave Jev a reranker's job.
How easily one added sentence pushes a wrong page up these rankings is in One sentence to the top 5.